Four NVIDIA DGX Sparks, four direct ConnectX‑7 cables, no Ethernet or InfiniBand switch in the data path, and GLM‑5.3‑Flash NVFP4 serving at 68.6–70.3 tokens/s on prose, 126.6–138.8 tokens/s on code, and 4,499 tokens/s on a 21.9K-token cold prefill.
That is the result I reached on October 10, 2026. The interesting part is not just that the four-node ring works. It is that it is faster than the same model on my three-node full mesh, uses the stock NCCL 2.30.7 build, keeps quality intact, and exposes a 4.24M-token KV pool, without buying a switch.
The repository, launchers, fabric setup, tests, and benchmark battery are in calvarado2004/sparks.
Short version. Moving from three Sparks in a triangle to four Sparks in a switchless ring improved single-stream code decode by 34–47%, prose by 40–43%, 21.9K-token prefill by 53%, and doubled the useful KV pool from 1.85M to 4.24M tokens. A real 54,214-token one-shot HTML generation ran at 80.4 tok/s.
Why try a ring at all?
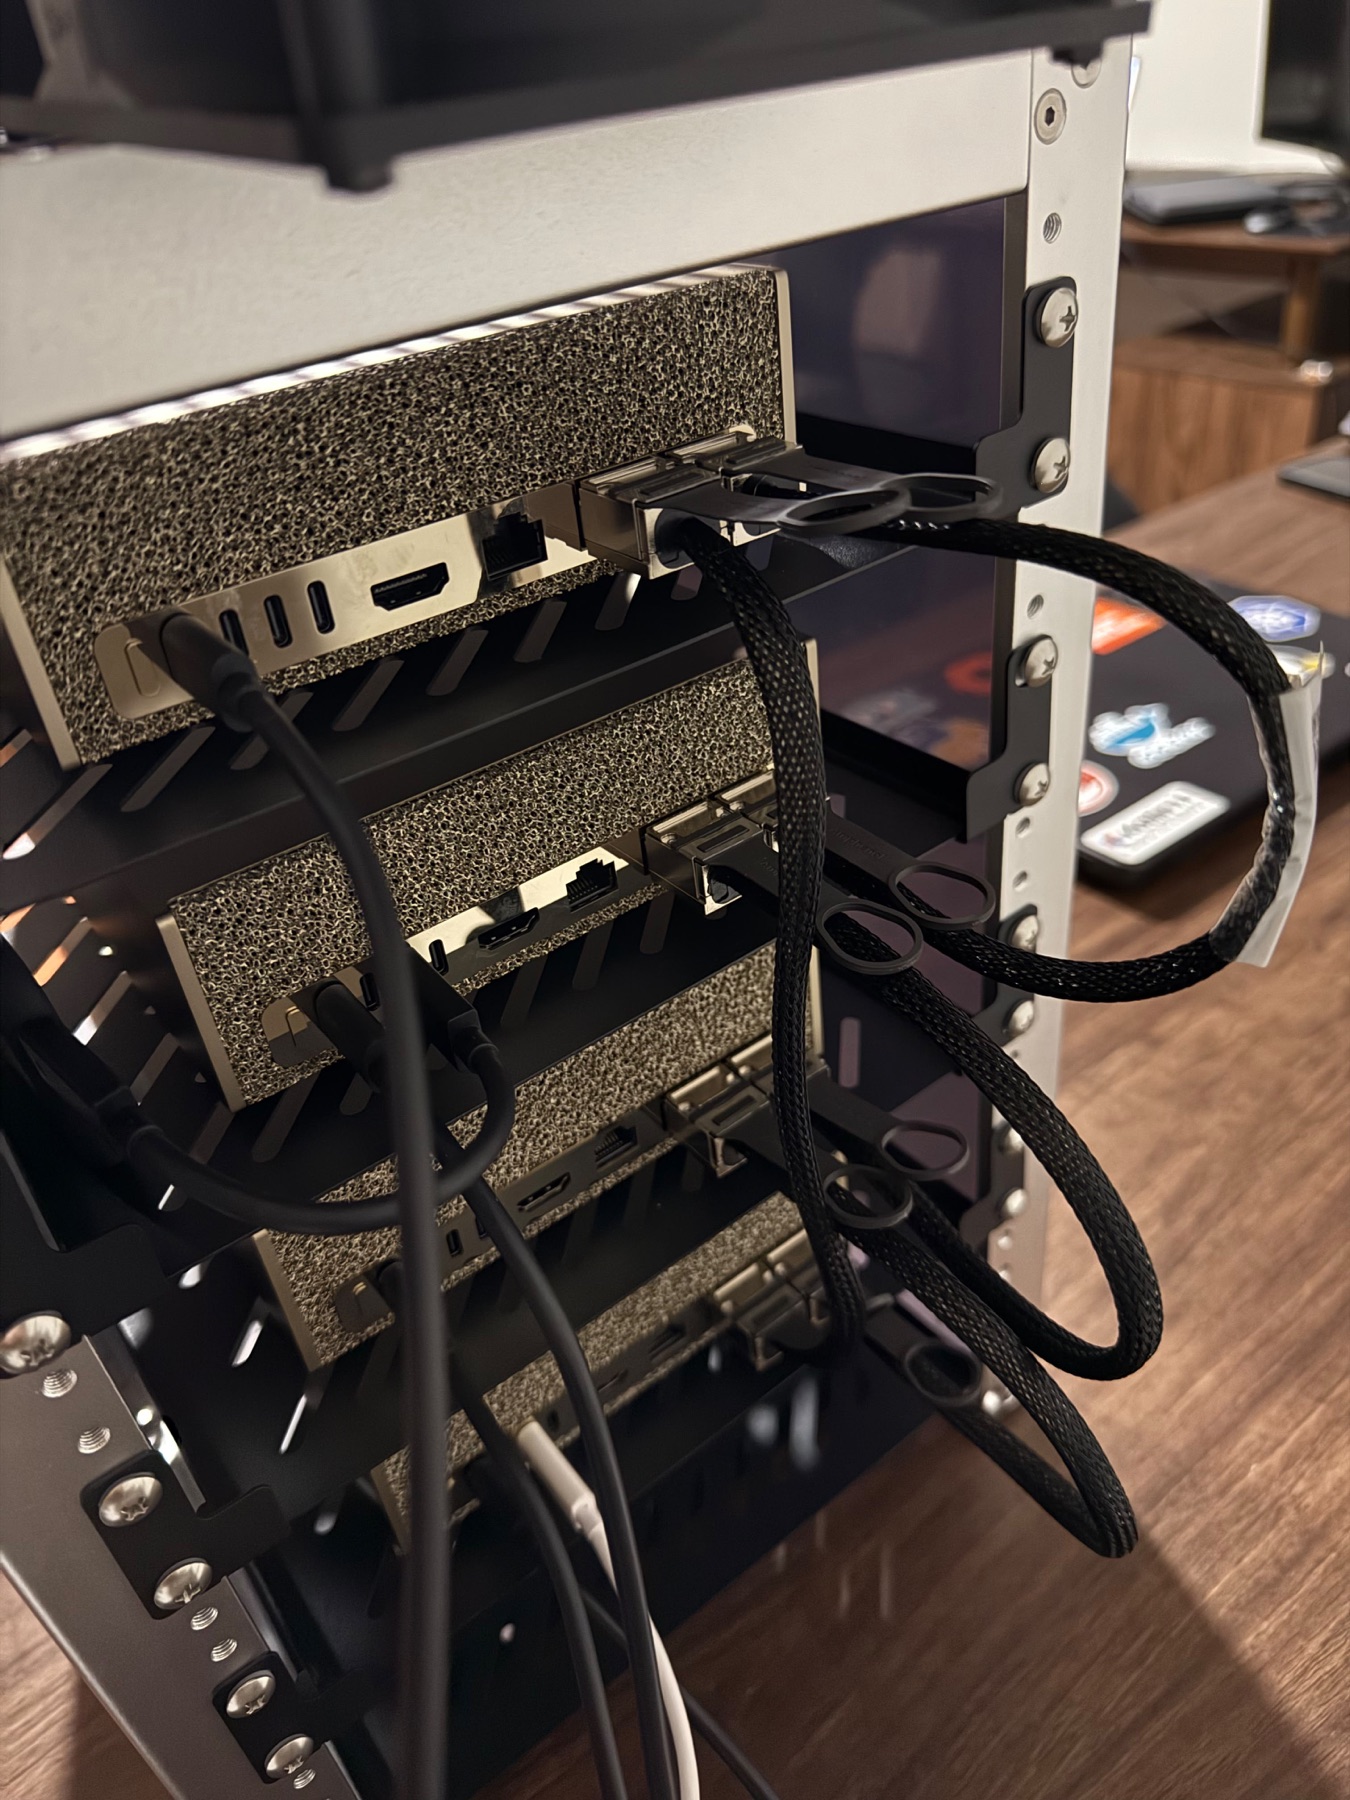
My previous GLM‑5.3‑Flash card used three Sparks in a full mesh. With three nodes, every rank can have a direct cable to every other rank, which is a comfortable topology for tensor parallelism. Adding a fourth node changes the geometry. A full four-node mesh needs six links, but four Sparks provide a natural four-link loop:
spark-329f → spark-355d → spark-c049 → spark-3d38 → spark-329fOpposite ranks have no cable between them. That is the part that makes a switchless four-node deployment look suspicious at first: ordinary NCCL setup likes to construct more than one collective pattern, and RoCE is not normal routed IP traffic. Linux ip_forward does not magically turn a middle Spark into a RoCE router.
The useful observation is that tensor-parallel all-reduce does not require a full mesh if the collective is deliberately constrained to the physical ring. Each rank only needs to send to its next neighbor and receive from its previous one. The two-hop case is handled as a relay through the intermediate rank.
The physical and logical topology
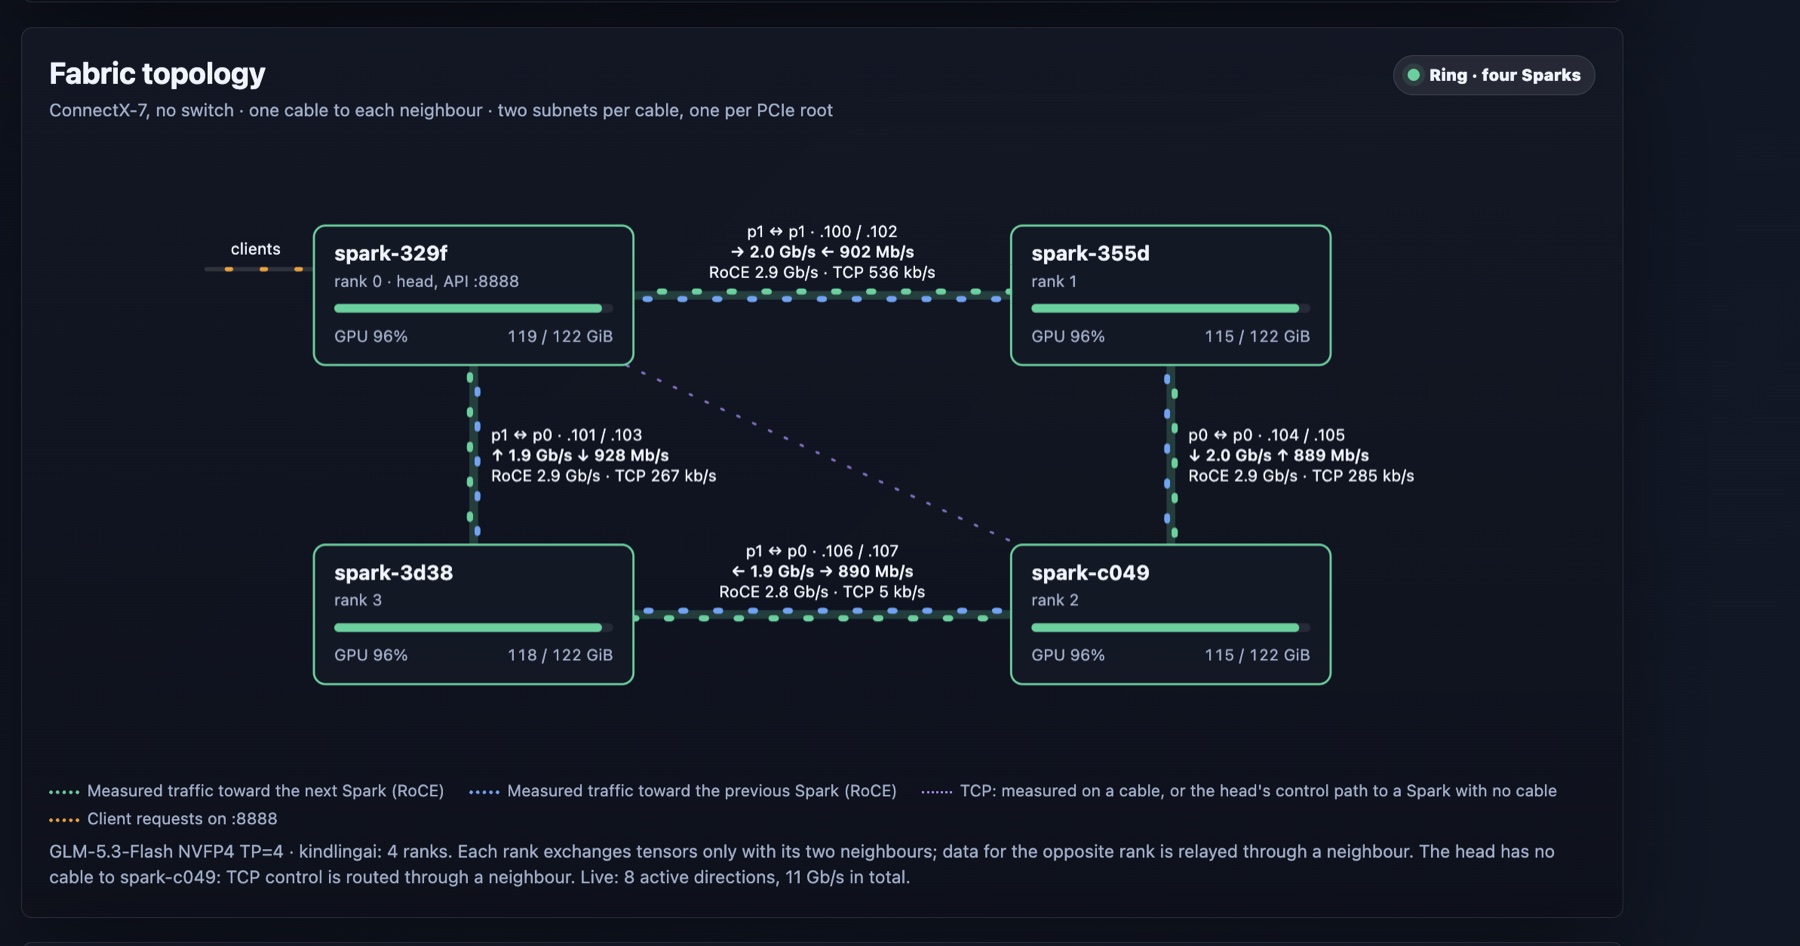
Each cable carries two subnets, one for each PCIe root behind the ConnectX‑7. The four physical links are:
| Cable | Cages | PCIe root A | PCIe root B |
|---|---|---|---|
| 329f ↔ 355d | p1 / p1 | 192.168.100.0/24 |
192.168.102.0/24 |
| 355d ↔ c049 | p0 / p0 | 192.168.104.0/24 |
192.168.105.0/24 |
| c049 ↔ 3d38 | p1 / p0 | 192.168.106.0/24 |
192.168.107.0/24 |
| 3d38 ↔ 329f | p1 / p0 | 192.168.101.0/24 |
192.168.103.0/24 |
The rank order follows the cable order. That sounds obvious, but it is load-bearing: the ring implementation defines rank r - 1 as “previous” and rank r + 1 as “next.” A rank order that does not match the actual cables gives the collective a neighbor it cannot reach.
There are two different network stories in this setup:
- RoCE data-plane traffic stays strictly neighbor-to-neighbor. It is never routed by Linux.
- TCP control traffic—NCCL bootstrap, Gloo, and ZeroMQ decode-step coordination—can cross to the opposite rank through static routes and an explicit forwarding rule.
That separation matters. Treating RoCE like normal IP was one of the tempting dead ends.
How the collective works
I used the TP=RING4 path from kindlingai/glm-5.3-flash-gx10, pinned at commit 45b438b. The launcher tells the image which interfaces face the previous and next ranks. Its fabric setup then builds three pieces:
1. NCCL is forced to the Ring algorithm with a hand-written channel graph. Each channel receives on the previous port and sends on the next port. 2. arx handles the small all-reduces on direct neighbor queue pairs. At world size four, the proxy forwards the partial from the previous rank to the next rank. 3. arxbig handles larger reduce-scatter and all-gather traffic, splitting the opposite-rank path across both directions of the ring.
The essential environment is:
NCCL_ALGO=Ring
NCCL_IB_MERGE_NICS=0
NCCL_CROSS_NIC=1
NCCL_IB_SUBNET_AWARE_ROUTING=1
NCCL_IB_SUBNET_PREFIX_LEN=24
VLLM_ARX_RING=1
The important discovery on my real cables was NCCL_IB_SUBNET_AWARE_ROUTING=1. The upstream graph by itself failed: stock NCCL selected one device per channel for both directions, so a sender sometimes tried to reach its next neighbor through the port physically connected to its previous neighbor. Every rank eventually reported ibv_modify_qp ... Connection timed out.
With subnet-aware routing and a /24 prefix, the sender chooses the device that shares the receiver’s cable subnet. The same NCCL 2.30.7 build then passed from 1 MiB through 256 MiB, reaching 190 Gb/s bus bandwidth at 256 MiB. No patched NCCL was required, and both PCIe roots carried traffic.
Before starting vLLM I tested the transports in isolation:
| Test | Result |
|---|---|
| arx correctness | 480 checks per rank, 0 failures |
| arx all-reduce | 15.5 µs at 8 KB, 27.0 µs at 64 KB, 97.4 µs at 512 KB |
| arxbig all-gather | 177–180 Gb/s at 8–32 MB |
| arxbig reduce-scatter | 112–115 Gb/s at 8–32 MB |
| NCCL ring | correct at 1–256 MiB, 190 Gb/s bus bandwidth at 256 MiB |
First boot
The first boot took 717 seconds. That included 342 seconds to load the checkpoint, 99.5 seconds to write 45.3 GiB of tensor-parallel snapshots on every node, and 69 seconds for CUDA graph capture. Later starts can reuse the snapshots; the first boot is the expensive one.
The model uses the stock GLM‑5.3‑Flash NVFP4 checkpoint and stock drafter. Unlike TP=3, TP=4 needs no padded checkpoint: the attention heads, experts, and vocabulary divide cleanly by four.
With a 26 GiB KV-cache pin, vLLM exposed 4,241,096 KV tokens—enough for four simultaneous requests at roughly one million tokens each. That is 2.3× the 1.85M-token pool I had on TP=3.
TP=4 ring versus TP=3 mesh
I ran the same detached test battery against both cards: count-to-100, corruption probes, tool use, multi-turn prefix reuse, video input, long-context needle searches, and two repetitions of the decode benchmark twelve minutes apart.
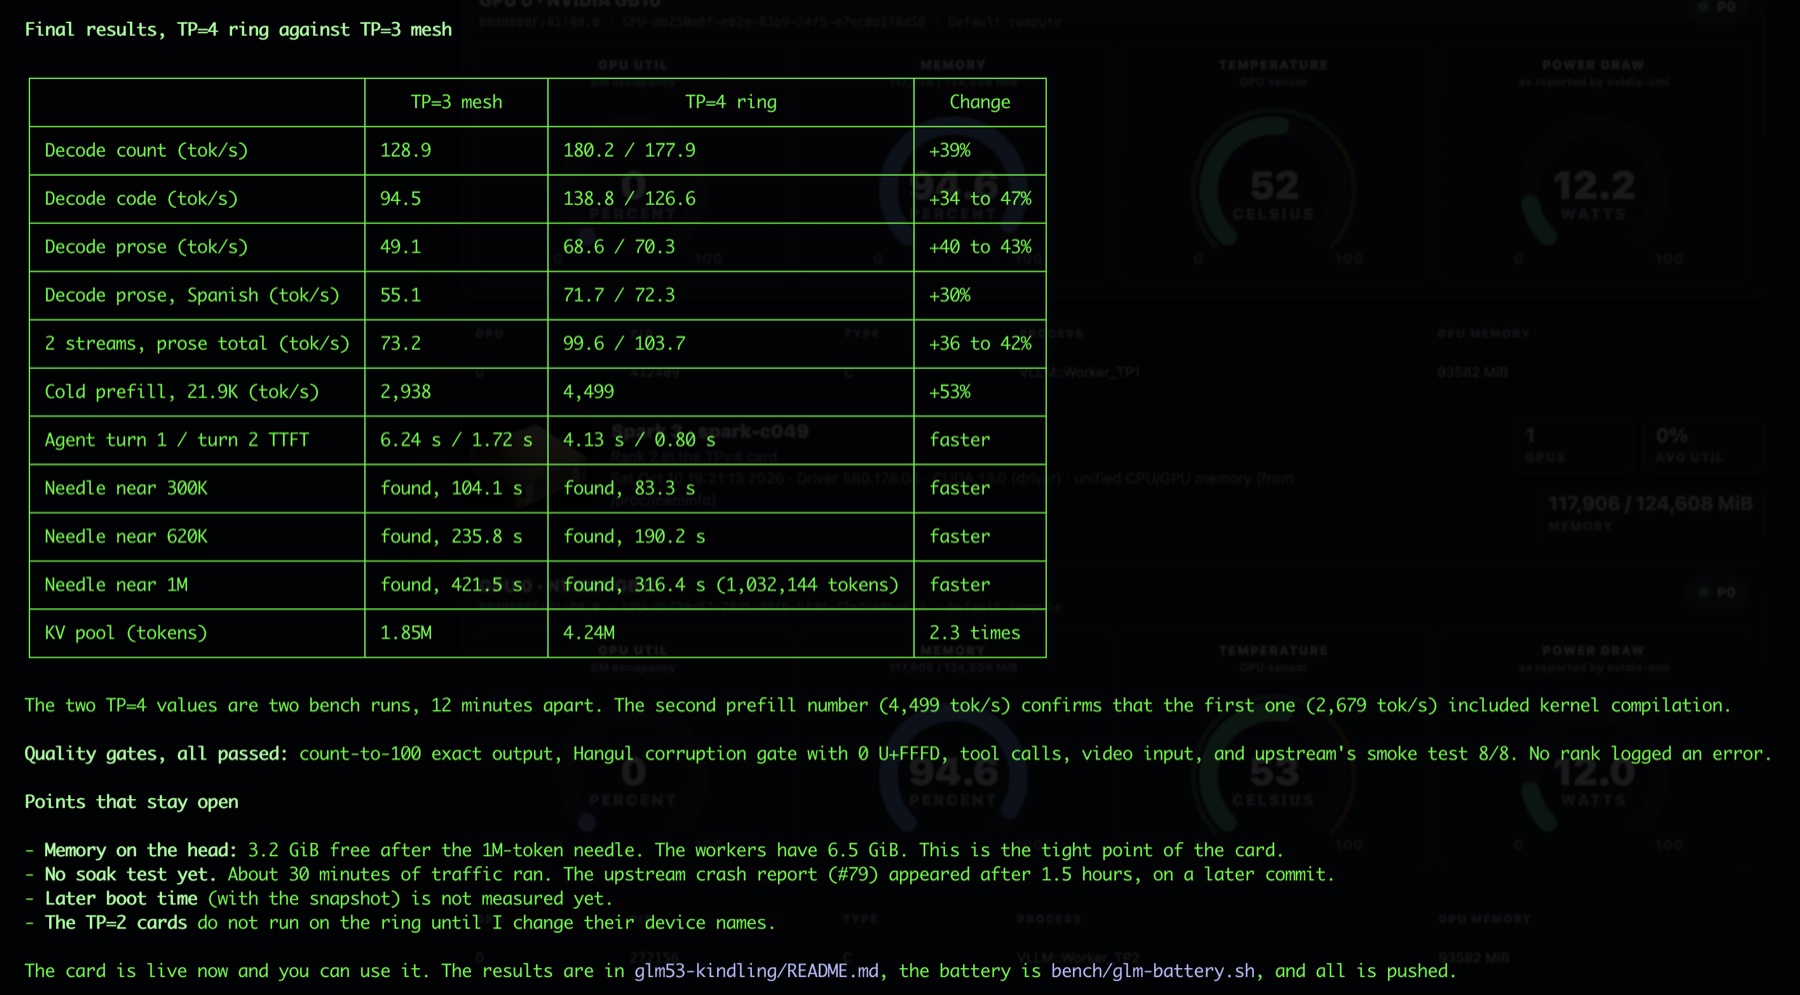
| Workload | TP=3 mesh | TP=4 ring | Change |
|---|---|---|---|
| Count decode | 128.9 tok/s | 177.9–180.2 tok/s | +39% |
| Code decode | 94.5 tok/s | 126.6–138.8 tok/s | +34–47% |
| English prose decode | 49.1 tok/s | 68.6–70.3 tok/s | +40–43% |
| Spanish prose decode | 55.1 tok/s | 71.7–72.3 tok/s | +30% |
| Two-stream prose aggregate | 73.2 tok/s | 99.6–103.7 tok/s | +36–42% |
| Cold prefill, 21.9K prompt | 2,938 tok/s | 4,499 tok/s | +53% |
| Turn 1 / turn 2 TTFT | 6.24 s / 1.72 s | 4.13 s / 0.80 s | faster |
| Needle near 1M | 421.5 s | 316.4 s | faster |
| KV pool | 1.85M tokens | 4.24M tokens | 2.3× |
The ring is not “almost as good as a switch” in some abstract sense. On this model and this hardware it is fast enough that the fourth rank more than pays for the relay cost. The small-collective latency rises—8 KB arx all-reduce went from 12.2 µs on the three-node mesh to 15.5 µs on the four-node ring—but each rank holds 25% of the model rather than 33%, and the rest of the step gets faster.
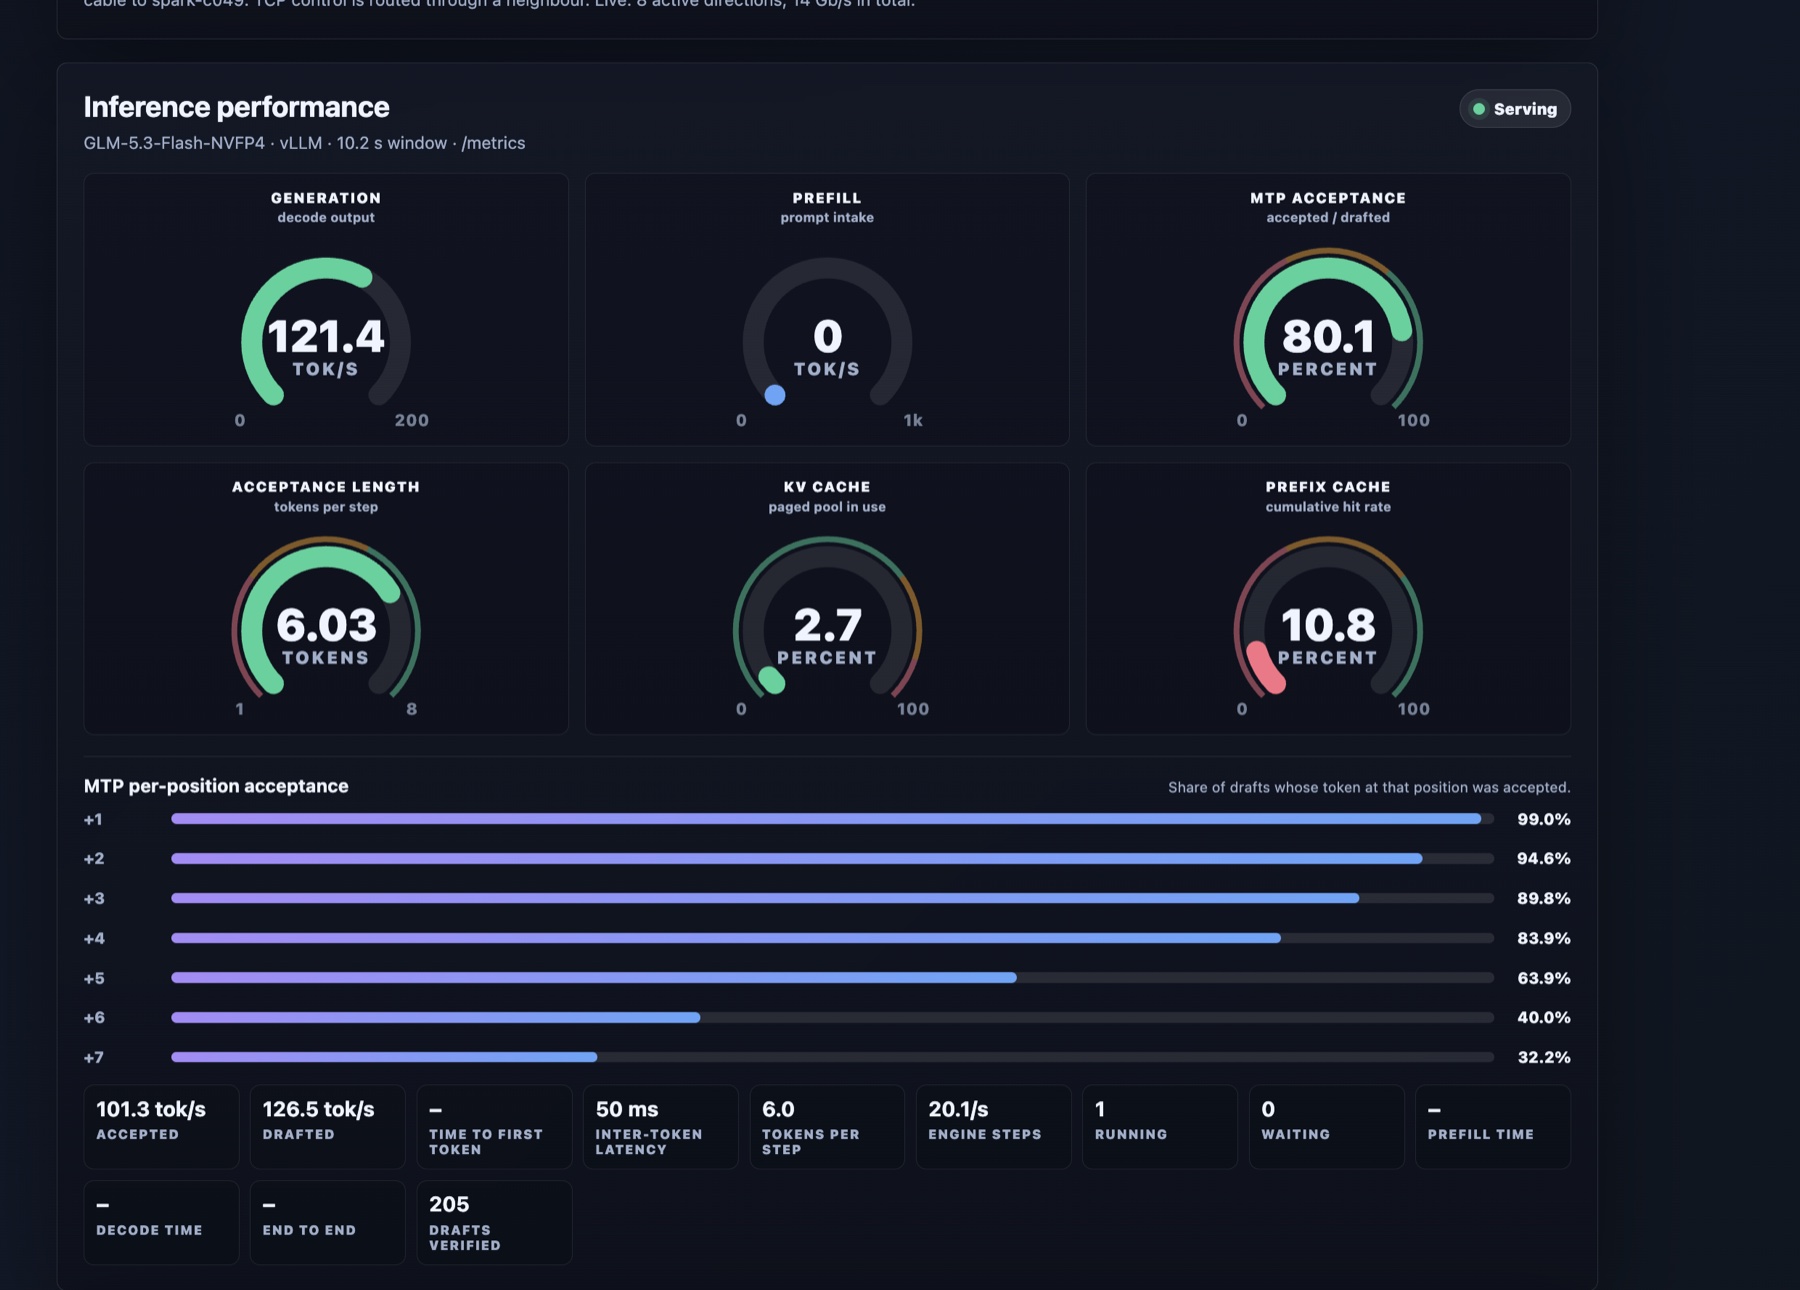
The one-shot test that mattered more to me
Synthetic prompts are useful because they are repeatable, but I also wanted a task that looked like actual work. I asked the model:
Generate me in a single HTML file a landing page for an AI technology blog/personal branding site, name Carlos Alvarado, professional design, JS, CSS.
It produced a complete 54,214-token HTML document in one response. The run was:
| Phase | Tokens | Time | Rate |
|---|---|---|---|
| Prompt | 44 | 0.822 s | 53.6 tok/s |
| Generation | 54,214 | 674.46 s | 80.4 tok/s |
| Total | 54,258 | 675.28 s | — |
That is eleven minutes and fifteen seconds for a large, self-contained page with responsive CSS and JavaScript—not a short code completion. The output is embedded below exactly as generated.
Interactive one-shot output — scroll inside the frame; links open separately.
Quality gates
Speed is only interesting if the fourth rank does not quietly change the model. The full battery passed:
- count-to-100 exact output, 3/3, with 0.88–0.95 draft acceptance;
- Hangul corruption probe, 0 replacement characters over three passes;
- tool-call probe;
- video-input probe using frames across time;
- upstream smoke test, 8/8;
- needle retrieval near 300K, 620K, and 1M tokens;
- no error line on any rank while serving.
The one warning worth recording was a single arx ... STALL message on every rank during CUDA graph capture. Boot continued immediately, and no stall appeared under serving traffic.
At the one-million-token needle, the head had only 3.2 GiB free. Workers retained 6.5–9.7 GiB. The head is therefore the tight point of the card, and I keep speech workloads on a worker.
What remains open
This is a working deployment, not the end of the investigation.
- The first validation run covered roughly 30 minutes of mixed traffic. A longer soak still matters because one upstream report saw a rank die after 1.5 hours on a later commit and a different RecoverSSM configuration.
- Snapshot-restore boot time still needs a clean measurement.
- TP=3 cannot run unchanged on this ring. Any three of the four nodes form a line, not a closed collective. Switching back to the triangle requires changing the cables and applying the mesh layout.
Those limits are operational, not hypothetical excuses. The card is live, has passed the quality battery, and has already generated long real outputs correctly.
The practical conclusion
For weeks I treated the absence of published four-Spark ring results as evidence that a switch was probably required. It was not. The working recipe was already latent in the upstream ring code; it needed the physical rank order, per-cable subnets, the right NCCL device selection on real cables, and separate treatment of RoCE and TCP.
The result is now my preferred GLM‑5.3‑Flash configuration:
- four DGX Sparks;
- direct ConnectX‑7 cables in a ring;
- no switch;
- stock NCCL 2.30.7;
- GLM‑5.3‑Flash NVFP4 with DFlash2;
- 68.6–70.3 tok/s prose, 126.6–138.8 tok/s code;
- 4.24M KV tokens;
- verified text, tools, long context, and video.
The biggest lesson is simple: a topology that is not widely documented is not the same thing as a topology that cannot work. Measure the actual transport, force the collective to match the cables, and test correctness independently from serving. Four Sparks on a ring are not a consolation prize. For this model, they are the fastest and most useful configuration I have run.
Code and reproducibility: calvarado2004/sparks/glm53-kindling · bench/glm-battery.sh · upstream report: kindlingai/glm-5.3-flash-gx10#88